Scarebox: an AI heckler for a Halloween fun run
A box by the course that looks at your costume and heckles you about it, in the voice of a pompous English gentleman. Offline, on a battery, at the Hopkinton Center for the Arts Halloween 5k.
I volunteered to build a “scarebox” for the Halloween 5k at the Hopkinton Center for the Arts. It’s a family fun run where most of the field, kids especially, runs in costume, so the brief more or less wrote itself: a box by the course that looks at your costume and heckles you about it as you go past.
So that’s what it does. A webcam watches the path, a vision model works out what you’re dressed as, and a pompous English gentleman called Sir Reginald yells a family-friendly line about it through a PA speaker further down the course. He’s a synthetic voice, nobody real. All of it runs offline on one small GPU box (an ASUS GX10, NVIDIA’s GB10 chip) off a camping battery.
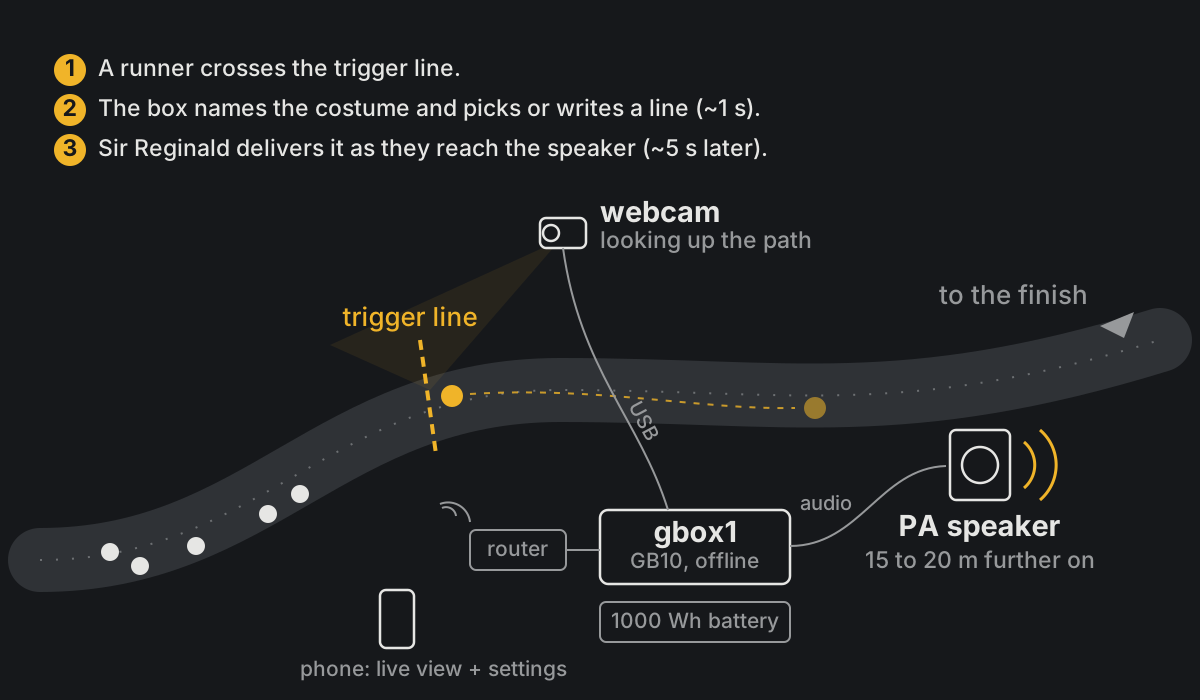
The camera sits upstream of the speaker on purpose. Judging a costume and picking a line takes a second or so, and the voice takes a few more, so by the time Sir Reginald gets going the runner is arriving at the speaker instead of disappearing off down the road.
People loved it. The generic lines got smiles, but when it named something specific about a costume, people looked genuinely surprised and delighted that the box had noticed them. The best one of the morning was a runner dressed as Frida Kahlo. There’s no pre-written line for Frida Kahlo, so the vision model recognised her, wrote one on the spot, the safety filter let it through, and out it came:
“Frida Kahlo’s artistry demands a final, glorious dash, darling!”
Nice.
How it works
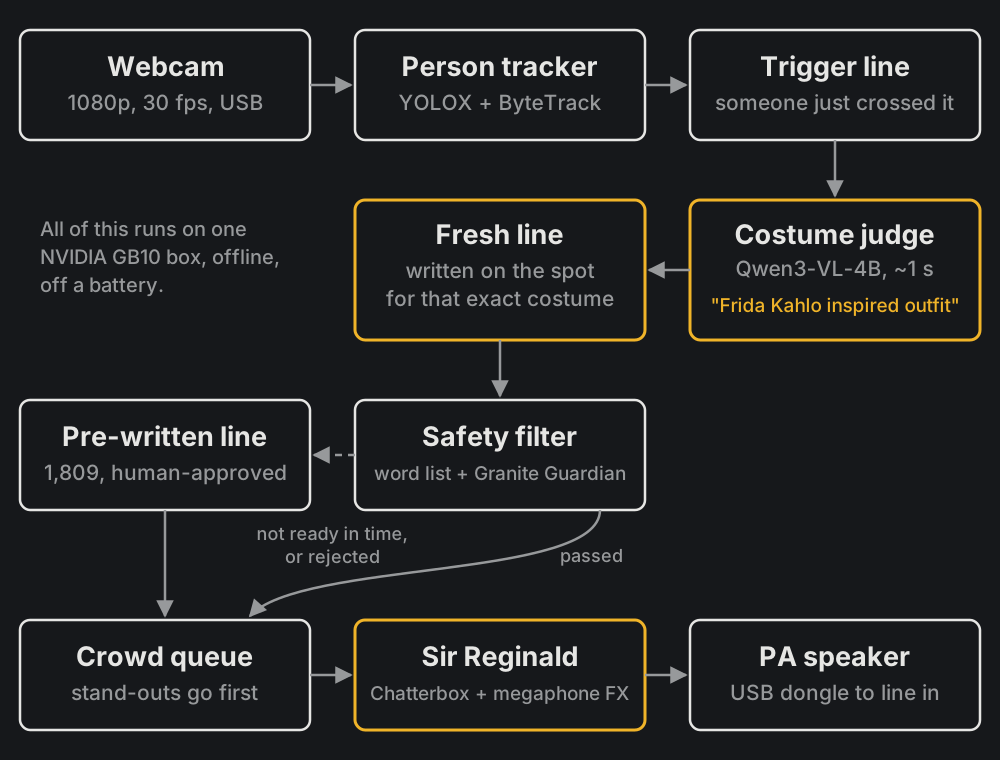
A tracker follows everyone in frame, and when someone crosses a line drawn across the picture, the costume judge (Qwen3-VL-4B, running locally) gets a crop of them and says what they’re wearing. Whenever it’s free, the same model also has a go at writing a fresh line for that exact costume, which has to get through a safety filter (a word list, then IBM’s Granite Guardian) before it can be spoken. If the fresh line is ready in time and passes, that’s what you hear. If not, it falls back to one of 1,809 pre-written lines, every one read and approved by a human and voiced ahead of time, so they’re instant. On race day that split came out at 29 fresh lines to 75 pre-written ones. The voice is Chatterbox cloning a synthetic reference clip, with a megaphone effect on top.
Crowds are the hard bit
One runner at a time is easy. A pack of kids arriving all at once is not, and one voice can only get a line out every five or six seconds.
I tuned it indoors by pointing the webcam at a tablet playing YouTube videos of Halloween parades, which turn out to be perfect test data: a steady stream of kids in costume, all day. Replaying that through the real pipeline and scoring who actually got named, the fixes that mattered were picking the stand-out costume in a group instead of saying something vague about the whole group, getting the judge to rate how eye-catching each costume is, and letting a line start a bit later (the speaker’s downstream anyway) so the good ones stopped expiring in the queue.
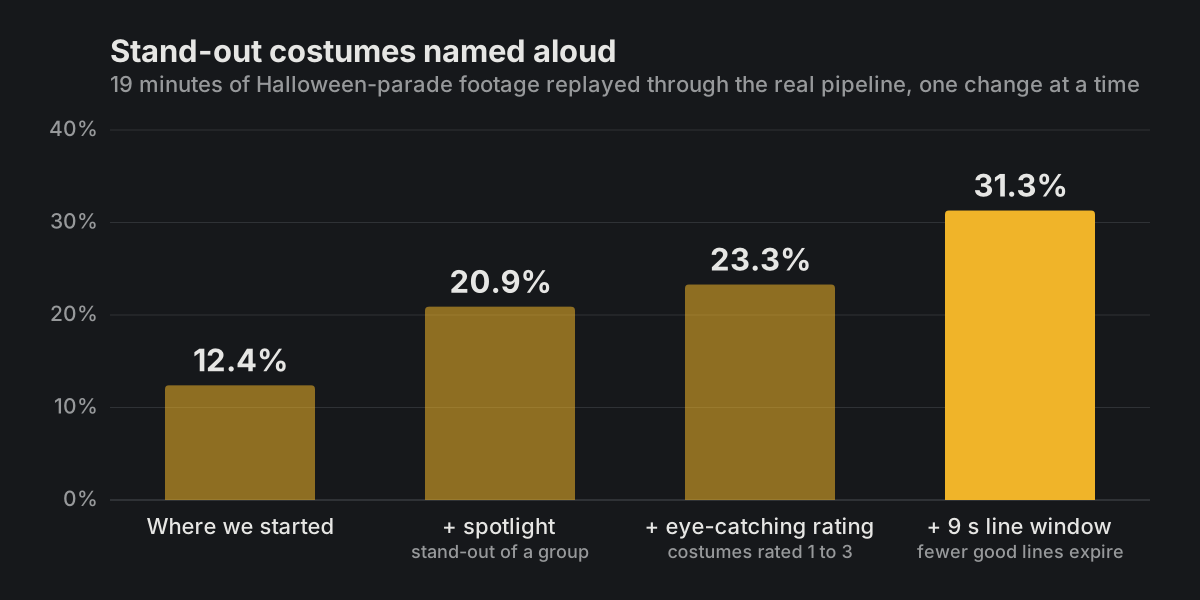
31% isn’t perfect, but in a crowd the box is now spending its voice on the costumes people actually point at.
Race day
Box on a 1000 Wh power station, a travel router so my phone could see the camera and tweak settings, webcam up the path, PA 15 to 20 m down it. Power on, wait two minutes for Sir Reginald to announce he’s seated.
Except he didn’t. The webcam’s USB-C plug wasn’t seated properly, its fast link never came up, and the box sat there quietly restarting instead of telling anyone the camera was missing. That’s a bug, and it’s issue #1. Reseated the plug, and it ran for two hours without anyone touching it: 104 lines, 29 of them written on the spot.
Building it
Most of it was about a day of vibe coding. I did the design and made the calls, and Claude Code wrote most of the code, tests and docs. Another day went on tuning against the parade videos.
The code is on GitHub at voronerd/scarebox. It’s built for one specific box, but it’s documented well enough that you (or your coding agent) could adapt it to yours. If you build one for your own fun run, let me know how it goes.
Photos to come.